Why a Green Internal Audit Doesn't Guarantee a Strong Ofsted Outcome
A manager's briefing on the gap between what an audit records and what an inspector judges under EYFS 2026 and the Ofsted Early Years Inspection Toolkit 2026.
Written byAbraham
Published
Reading time19 min read
Every nursery manager knows the feeling of a clean audit. The spreadsheet is green, the policies are dated, the training matrix is complete and the monthly checks have been signed. It is reasonable to read that as a forecast: if everything we measure is in order, the inspection should go well. This briefing argues that the forecast is weaker than it feels, and explains why, using research on self-evaluation, inspection validity and organisational safety, alongside the structure of the 2026 framework.
The point is not that internal audits are worthless. They are among the most useful tools a manager has. The point is that an audit and an inspection answer different questions. An audit usually asks whether something exists: is the policy in place, was the check done, is the certificate current. An inspection under the 2026 toolkit asks, in effect, what difference it makes for children: how well the curriculum is taught, how children are achieving, how they behave, how safe and well they are, and how well the setting is led. Existence is necessary for the second set of questions, but it is nowhere near sufficient. A green audit can therefore sit alongside a modest judgement, and owners who do not understand why are the ones most likely to be surprised.
The sections below set out the theory behind that gap, map it onto the six evaluation areas and the separate safeguarding judgement, and finish with practical changes to how an internal audit can be designed so that its colour means something.
The theory: why self-assessment drifts upward
The oldest explanation is psychological. Kruger and Dunning (1999) showed that people who perform least well on a task are also the worst at judging their own performance, because the skills needed to do the task well are the same skills needed to recognise good performance. Applied to a nursery, this does not mean managers are incompetent. It means that a manager's ability to see a weakness in, say, the quality of adult-child interaction depends on having a sharp internal picture of what excellent interaction looks like. Where that picture is blurred, a weak practice looks adequate and the audit records it as such.
A second explanation is structural. Self-evaluation is conducted by the people who are accountable for the result. Research on internal and external evaluation in schools has repeatedly found that the two do not line up neatly. Vanhoof and Van Petegem (2007), studying the Flemish system, argued that internal and external evaluation have different purposes, different standards and different audiences, and that treating one as a rehearsal for the other produces false assurance. Ehren and Visscher (2006) reached a compatible conclusion about inspection more broadly: the effect of inspection on a school depends heavily on how the school perceives and responds to the framework, not simply on the framework's content. Nurseries that audit against the wrong picture of the framework will score well against a standard the inspector is not using.
A third explanation concerns what happens when a measure becomes important. Campbell (1979) stated what is now called Campbell's Law: the more a quantitative indicator is used for decision-making, the more it is subject to corruption pressures and the more it distorts the processes it is meant to monitor. Bevan and Hood (2006), analysing English health-sector targets, described the same mechanism in public services: organisations hit the target and miss the point. They found that "gaming" was not always cynical. Often it was a rational adaptation by well-meaning people to a measure they were held to. In early years, Roberts-Holmes (2015) documented how datafication reshaped practice as settings oriented themselves to what could be recorded and reported. An internal audit that is reviewed by an owner, a trustee or a franchise head office is, in effect, a target, and the same dynamics apply.
Finally, there is the problem of the invisible. Reason (2000) described how accidents in complex systems rarely come from a single failure; they arise when latent weaknesses in several layers of defence line up. His image of holes in slices of Swiss cheese is useful here because an audit tends to inspect the slices, not the holes. A policy exists (the slice is present), but whether staff follow it at seven in the morning with two people absent is a hole that no document check reveals. Weick, Sutcliffe and Obstfeld (1999) described high-reliability organisations as those that stay preoccupied with failure, reluctant to simplify and sensitive to operations. A green audit, read as good news, encourages precisely the opposite habit: simplification and complacency.
What an internal audit measures, and what inspection judges
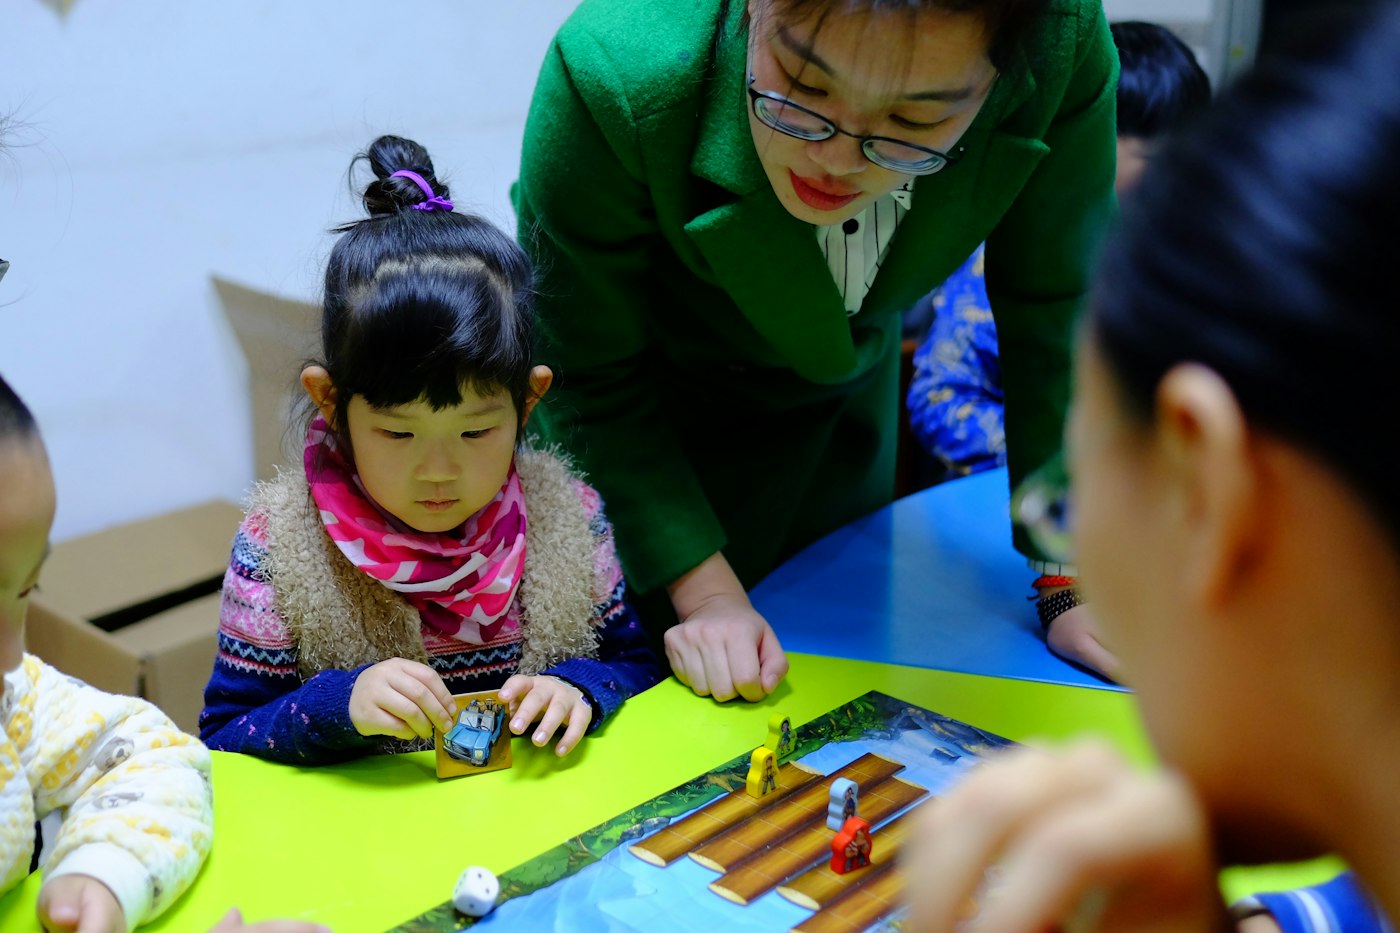
It helps to be precise about the types of evidence involved. Most nursery audits are weighted towards what researchers call structural quality: ratios, qualifications, premises, documentation, policies and certificates. These are visible, countable and stable. Inspection under the 2026 toolkit puts far more weight on process quality: what actually happens in the interactions between adults and children, in routines, in play and in conversation.
The research on early years quality is consistent that the two are only loosely related. Sylva and colleagues (2006), in the Effective Provision of Pre-School Education study, found that the quality of adult-child interaction and the pedagogical approach were stronger predictors of children's outcomes than many structural features. Slot, Leseman, Verhagen and Mulder (2015) similarly found that, in Dutch settings, structural characteristics were associated with process quality only modestly, with process quality the aspect most closely tied to what children experience. The practical implication is uncomfortable: a setting can score perfectly on every structural checklist and still deliver teaching that is thin, routine-driven or unresponsive.
Inspectors spend their time watching interactions like this one. Process quality is what an audit of structural features tends to miss. Photo: Jerry Wang on Unsplash
This matters because the 2026 toolkit is built around how well provision works for children. It is not a document inspection. Inspectors will see the paperwork, but they spend their time watching practice, talking to children and staff, and testing whether what leaders say is happening is actually visible on the floor. If an audit cannot capture that, it can only ever be a partial forecast.
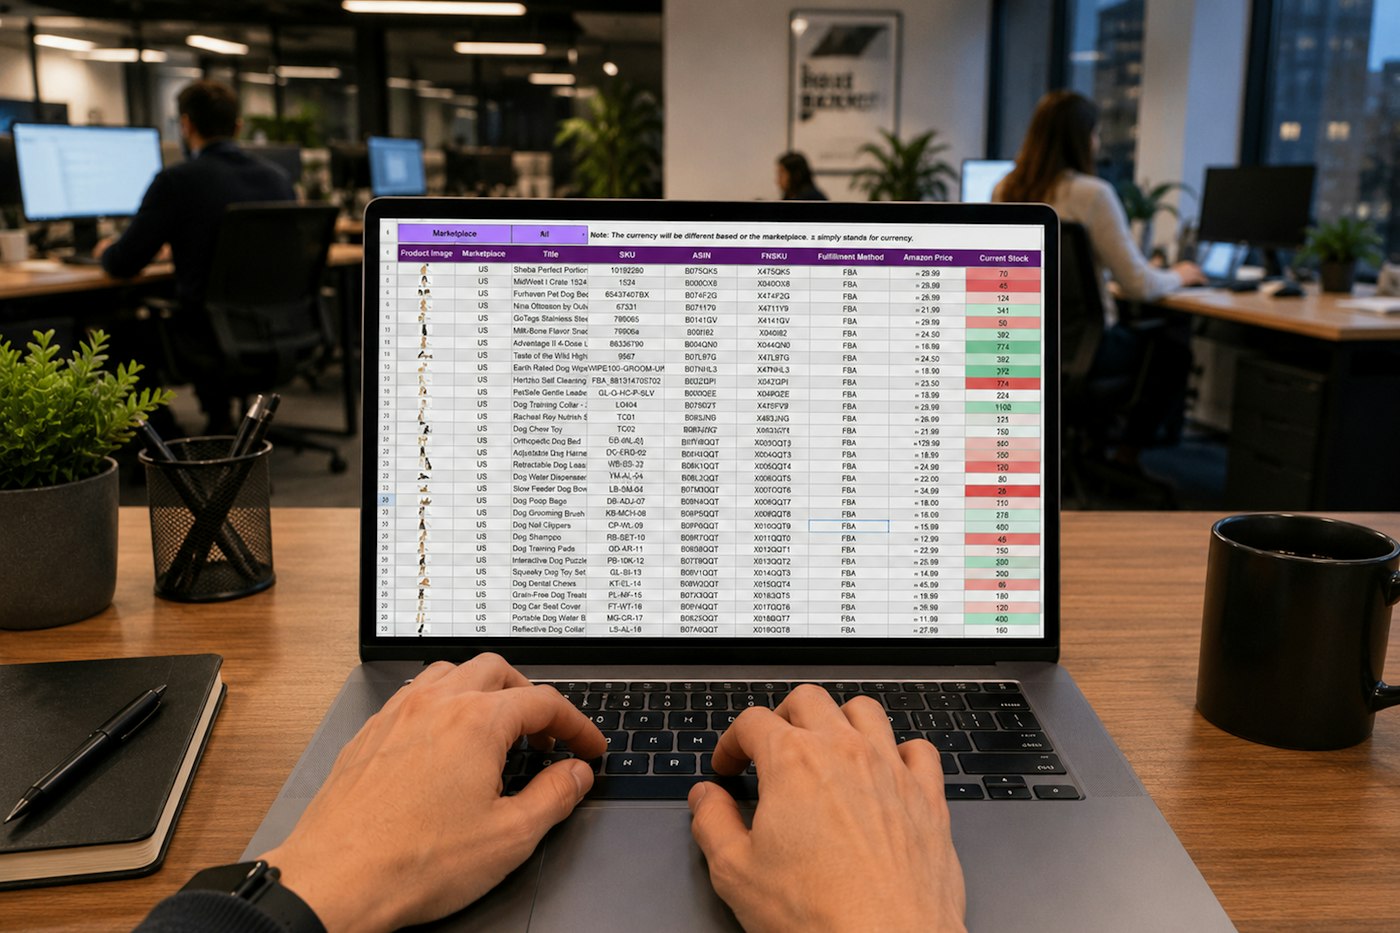
A related warning comes from the study of composite indicators. Munda and Nardo (2009) showed that the way in which separate indicators are combined into a single score embeds value judgements, and that "compensatory" aggregation, where strength in one dimension offsets weakness in another, can hide serious deficits. A nursery audit that produces an overall percentage or a single traffic-light colour is a compensatory measure by design. Fifty green items can drown out three amber ones, even when the three amber items are the ones that matter most to an inspector.
Fifty green items can drown out three amber ones, even when the three amber items are the ones that matter most to an inspector. Photo: Gorilla ROI Data Connector on Unsplash
The six areas and where audits go quiet
The 2026 toolkit evaluates six areas on a five-point scale: Inclusion; Curriculum and Teaching; Achievement; Behaviour, Attitudes and Establishing Routines; Welfare and Wellbeing; and Leadership and Governance. The grades run from Exceptional through Strong Standard and Expected Standard to Needs Attention and Urgent Improvement. A typical internal audit is comfortable with some of these areas and poor at others, which is where the gaps open.
Welfare and Wellbeing, and parts of Leadership and Governance, are the areas where audits tend to be most reliable, because they involve things that can be checked: risk assessments, accident records, first aid, food hygiene, staff supervision records, policy review dates. A manager who scores well here is probably right to feel reassured, although the checks must still be tested against practice.
Curriculum and Teaching is where audits begin to lose resolution. Most settings can show a curriculum document and a planning format. Few can show, through audit, that every practitioner understands the intent, sequences learning deliberately, and adapts in the moment. Hofer, Holzberger and Reiss (2020), reviewing evidence on the evaluation of teaching quality, showed that reliable judgement of teaching requires structured observation by trained observers using clear criteria, and that single observations and self-reports are weak guides. An audit that asks "is there a curriculum?" will return green. An inspector asking "what are children learning here, and how do you know?" will return a different answer.
Achievement is subject to the same problem. Many nurseries track progress through frequent assessment, and the tracker is often the principal audit evidence. But as Roberts-Holmes (2015) argued, data collection can drift away from teaching and become an end in itself. Attainment data that is internally generated and internally moderated shares the same blind spots as the audit. An inspector will triangulate: does what the tracker says match what children can do, say and show during the visit?
Inclusion and Behaviour, Attitudes and Establishing Routines are the areas where audits are often thinnest. Both depend on the culture of the room: how a practitioner responds to a child with a different communication style, whether routines are calm and purposeful, whether expectations are consistent. These are observed, not documented. A behaviour policy in the file says very little about whether a child in the baby room is comforted promptly, or whether a child with an identified need is genuinely included in the day. Audit tools rarely sample these experiences at the level of detail inspectors will see.
Safeguarding: a separate threshold
One feature of the 2026 approach deserves its own section because it alters how a green audit should be read. Safeguarding is judged separately, as Met or Not Met, and is not blended into the graded areas. That design choice is deliberate. A setting cannot compensate for a safeguarding failure by performing well on curriculum, and a strong safeguarding finding does not lift a weak curriculum judgement.
For managers, this has two consequences. First, the safeguarding portion of an audit must be treated as a threshold test, not as one component of an average. A score of ninety-five percent overall with one unresolved concern about, for example, the way a low-level concern is recorded and acted on, is not a ninety-five percent position. It is a risk of Not Met. Reason's (2000) model explains why: serious harm is generally produced by the alignment of failures, and a single known hole that has not been closed is exactly the kind of latent condition that, combined with another, becomes dangerous.
Second, the culture on which safeguarding relies cannot be audited from documents alone. Edmondson (1999) demonstrated that teams differ in psychological safety, the shared belief that it is safe to speak up, and that this predicts whether errors are reported and learned from. Morrison and Milliken (2000) described organisational silence, where employees withhold concerns because they expect them to be unwelcome or ineffective. In a nursery, silence may mean a practitioner who noticed something but did not raise it. Guldenmund (2000), reviewing the literature on safety culture, noted how difficult it is to measure through formal instruments, precisely because the attitudes and assumptions that matter are rarely written down. A green audit tells you that procedures exist. It does not tell you whether the person with the worry feels able to use them.
Case-review research points in the same direction. Munro (2011), in her review of child protection in England, argued that systems oriented to compliance and procedure can crowd out professional judgement and learning, so that the system becomes better at demonstrating that it followed the rules than at protecting children. A nursery that is meticulous about forms but uncertain about thresholds is in the same trap.
When the audit becomes the target
Where an audit is used to report upwards, to an owner, a franchisor, a local authority or a lender, its meaning begins to shift. Staff learn what gets marked green and begin to produce it. This is not necessarily dishonest. A room leader who has been told that every child must have an up-to-date next step will make sure that every child has one, perhaps written quickly and generically. The audit tick is earned. The educational substance may be thin.
Perryman (2006) described a related phenomenon in schools under inspection, which she termed "performativity": a state in which staff stage the performance of compliance in order to meet external expectations, and in which the staged performance gradually replaces the underlying practice. Bevan and Hood (2006) distinguished between what they called "reactive gaming," where organisations deliberately manipulate figures, and the more common pattern in which the measure simply reshapes what people spend their time on. In both cases, an audit that is stable and predictable can be learned.
Mannion and Davies (2015), writing about cultural factors in quality and safety in health care, observed that organisations often assess culture through surveys and audits that are themselves products of the culture, and so tend to confirm what leaders already believe. For a nursery owner, the equivalent is an audit written by the manager, completed by the manager and reviewed by the manager. It would be astonishing if it disagreed with its author.
None of this is an argument for abandoning measurement. It is an argument for designing audits so that they are difficult to game and honest about what they cannot see. That means sampling rather than universal checking, varying the focus from month to month, drawing on evidence the person being audited does not control, and, above all, separating the person who writes the standard from the person who applies it.
Inspector variability and the limits of prediction
A further reason a green audit does not guarantee a strong outcome is that inspection itself is not perfectly reproducible. Bokhove, Jerrim and Sims (2023) examined the reliability of school inspection judgements in England and found that, even under a standardised framework, there is a degree of inconsistency between inspectors and inspection teams. This is not a criticism of inspectors; it is a feature of any human judgement exercised on complex evidence in a short time. A new framework adds further uncertainty, because inspectors, like the settings they visit, are still forming a shared understanding of what each grade looks like in practice.
Gigerenzer and Gaissmaier (2011) showed that people under time pressure rely on simple heuristics, and that these can be accurate but are sensitive to which cues are salient. On an inspection day, the cues that tend to be salient are those that are visible in the first hours: the atmosphere of the rooms, the way children and adults interact, how leaders talk about their setting, and whether practitioners can explain what they are doing and why. Tversky (1972) described elimination by aspects, where a choice is made by successively screening out options on the most important attribute. Applied loosely to inspection, a serious weakness on a high-priority attribute can lead to a poorer overall judgement than a balanced average would suggest. This is another reason the compensatory logic of an audit score is a poor guide.
The practical lesson is humility. An audit can reduce the odds of an unwelcome surprise, but it cannot remove them. What it can do is ensure that, whatever the grade, leaders understand why they received it and can show that they were already working on the areas the inspector identifies.
What this means in practice for managers and owners
First, audit against the toolkit, not against last year's checklist. Map each audit line to one of the six areas and to the separate safeguarding judgement. If a line cannot be mapped, ask why it is there. If an area has no lines, you have found a blind spot.
Second, add observation. Sample practice in every room each month using a short structured prompt, such as: What is this child learning right now? How does the adult know? What would an inspector see if they stood here for twenty minutes? Following Hofer and colleagues (2020), train the observers and use the same criteria each time, and avoid relying on a single observation. Pair managers from different rooms or, where possible, from different settings, so that no one grades their own room.
Third, stop averaging. Report safeguarding as Met or Not Met, with the evidence for each. Within the six areas, report the weakest element first, not the strongest. Replace an overall percentage with a short list of the three biggest risks and what is being done about each. This follows the logic of the non-compensatory design that both Munda and Nardo (2009) and the 2026 framework imply.
Fourth, test the culture. Ask staff, anonymously and regularly, whether they feel able to raise concerns, whether they have seen something they did not report, and whether the last concern they did raise was acted on. Edmondson's (1999) work suggests that these responses will tell you more about your real safeguarding position than the safeguarding policy review date. Ask children and parents too, and record what they say in their own words.
Fifth, get an external challenge. Invite a peer manager, a local authority adviser, an independent consultant or a governor to audit a sample of rooms using the toolkit. The point is not to pay for reassurance. It is to introduce someone whose judgement is not shaped by your own investment in the answer, which is the exact gap that Vanhoof and Van Petegem (2007) identified between internal and external evaluation.
Sixth, test the data. Choose five children and ask whether the tracker, the observation notes, the planning and what the child can do today all tell the same story. If they do not, the discrepancy is a finding, not an embarrassment. Roberts-Holmes (2015) warned that data can float free of practice; this test pulls it back.
Seventh, use amber honestly. An audit culture in which amber is seen as failure will produce green. Make it clear to staff and to any owner or head office that amber, reported early with a plan, is a sign of a healthy system. Weick and colleagues (1999) would call this a preoccupation with failure: not pessimism, but a refusal to let a good score close the question.
Amber reported early with a plan is a sign of a healthy system. An audit culture that treats amber as failure will produce green. Photo: Carter Saunders on Unsplash
Finally, prepare people, not paperwork. The best preparation for inspection is practitioners who can explain, in their own words, what they do and why. Run short, low-stakes conversations in which a practitioner talks through a child's learning, a risk assessment or a safeguarding scenario. This tests knowledge, builds confidence and will show you far more than a signature on a form.
Conclusion
A green internal audit is good news about your systems. It is not a forecast of your inspection grade, because it measures existence where inspectors measure effect, averages where the framework refuses to, and is written from the inside where judgement comes from outside. The research is consistent: self-assessment drifts upward, measures that matter become targets, structural quality is only loosely linked to process quality, and the culture that keeps children safe is largely invisible to document checks.
Managers and owners who take this seriously do not abandon their audits. They redesign them: mapped to the six areas, non-compensatory on safeguarding, grounded in observation, challenged from outside and honest about amber. Done that way, a green result begins to mean what everyone hoped it meant, and a less-than-green result becomes what it should be, an early and inexpensive warning.
References
Bevan, G. and Hood, C. (2006) 'What's measured is what matters: targets and gaming in the English public health care system', Public Administration, 84(3), pp. 517-538.
Bokhove, C., Jerrim, J. and Sims, S. (2023) 'How reliable are Ofsted inspections in England? An analysis of inspection reliability using a two-stage measurement approach', School Effectiveness and School Improvement, 34(4), pp. 419-441.
Campbell, D.T. (1979) 'Assessing the impact of planned social change', Evaluation and Program Planning, 2(1), pp. 67-90.
Edmondson, A. (1999) 'Psychological safety and learning behavior in work teams', Administrative Science Quarterly, 44(2), pp. 350-383.
Ehren, M.C.M. and Visscher, A.J. (2006) 'Towards a theory on the impact of school inspections', British Journal of Educational Studies, 54(1), pp. 51-72.
Gigerenzer, G. and Gaissmaier, W. (2011) 'Heuristic decision making', Annual Review of Psychology, 62, pp. 451-482.
Guldenmund, F.W. (2000) 'The nature of safety culture: a review of theory and research', Safety Science, 34(1-3), pp. 215-257.
Hofer, S.I., Holzberger, D. and Reiss, K. (2020) 'Evaluating school inspection effectiveness: a systematic research synthesis on 30 years of international research', Studies in Educational Evaluation, 65, 100864.
Kruger, J. and Dunning, D. (1999) 'Unskilled and unaware of it: how difficulties in recognizing one's own incompetence lead to inflated self-assessments', Journal of Personality and Social Psychology, 77(6), pp. 1121-1134.
Mannion, R. and Davies, H. (2015) 'Cultural factors in healthcare quality and safety: a review', Journal of Health Services Research and Policy, 20(3), pp. 183-191.
Morrison, E.W. and Milliken, F.J. (2000) 'Organizational silence: a barrier to change and development in a pluralistic world', Academy of Management Review, 25(4), pp. 706-725.
Munda, G. and Nardo, M. (2009) 'Noncompensatory/nonlinear composite indicators for ranking countries: a defensible setting', Applied Economics, 41(12), pp. 1513-1523.
Munro, E. (2011) The Munro Review of Child Protection: Final Report. A Child-Centred System. London: Department for Education.
Perryman, J. (2006) 'Panoptic performativity and school inspection regimes: disciplinary mechanisms and life under special measures', Journal of Education Policy, 21(2), pp. 147-161.
Reason, J. (2000) 'Human error: models and management', BMJ, 320(7237), pp. 768-770.
Roberts-Holmes, G. (2015) 'The "datafication" of early years pedagogy: "if the teaching is good, the data should be good and if there's bad teaching, there is bad data"', Journal of Education Policy, 30(3), pp. 302-315.
Slot, P.L., Leseman, P.P.M., Verhagen, J. and Mulder, H. (2015) 'Associations between structural quality and process quality in Dutch early childhood education and care settings', Early Childhood Research Quarterly, 33, pp. 64-76.
Sylva, K., Siraj-Blatchford, I., Taggart, B., Sammons, P., Melhuish, E., Elliot, K. and Totsika, V. (2006) 'Capturing quality in early childhood through environmental rating scales', Early Childhood Research Quarterly, 21(1), pp. 76-92.
Tversky, A. (1972) 'Elimination by aspects: a theory of choice', Psychological Review, 79(4), pp. 281-299.
Vanhoof, J. and Van Petegem, P. (2007) 'Matching internal and external evaluation in an era of accountability and school development: lessons from a Flemish perspective', Studies in Educational Evaluation, 33(2), pp. 101-119.
Weick, K.E., Sutcliffe, K.M. and Obstfeld, D. (1999) 'Organizing for high reliability: processes of collective mindfulness', Research in Organizational Behavior, 21, pp. 81-123.
Operations Director, Awake Early Years Consultancy
Former Ofsted Early Years Inspector, doctoral researcher and early childhood education and care consultant with over 16 years' experience across practice, inspection and leadership.